

Data infrastructure is the framework of hardware, software, and processes that collects, stores, processes, and secures data so it can be analyzed for business decisions. It typically combines databases, data lakes and warehouses, integration pipelines, governance policies, and on-premise, cloud, hybrid, edge, or hyper-converged deployments. With global data center spending projected to surpass $788 billion in 2026, modern infrastructure has become the foundation for scalable analytics, AI, and real-time insights.
Since data-intensive technologies become increasingly in demand, global data center spending is projected to surpass $788 billion in 2026, growing 55.8% year-over-year, according to Gartner’s latest IT spending forecast. This staggering number means that organizations are willing to collect, store, process, share, and analyze data in a well-structured manner to further use it for making crucial business decisions.
That is why data infrastructure and analytics work as a pair. The infrastructure keeps data accessible, accurate, secure and scalable, and the analytics tools layered on top of it help businesses spot trends, optimize operations, personalize customer experiences and test new ideas with evidence behind them.
What Is Data Infrastructure?
Data infrastructure is the combination of hardware, software and processes that collects, stores, integrates, governs and secures an organization’s data. It is the layer analytics depends on, so dashboards, reports and AI models can only be as reliable as the infrastructure that feeds them.
In practice, it brings together databases, data lakes and warehouses, integration pipelines, governance policies and the compute that runs them. Each of these pieces can be deployed in several ways, and the deployment model shapes how fast and how much data a company can analyze.
Data Infrastructure Examples
The most practical way to compare deployment models is by the analytics latency each one supports and the data volume it handles comfortably. With those two factors in mind, each type comes with a simple decision rule alongside its main advantages and limits.
Infrastructure Type | Best For | Choose It When | Key Advantages | Key Limitations | Example Providers / Technologies |
|---|---|---|---|---|---|
Traditional On-Premise | Strict data sovereignty needs, legacy systems, predictable workloads | Analytics runs on scheduled batches, data volume is large but predictable, and data must stay on owned hardware | Full hardware and data control, no third-party dependency | High upfront costs, limited scalability, requires in-house IT staff | Dell PowerEdge, HPE ProLiant, Cisco UCS |
Cloud | Cost-efficient scaling, global accessibility, minimal hardware management | Data volume grows or fluctuates, and analytics needs range from batch reporting to near-real-time dashboards | Pay-as-you-go pricing, built-in redundancy, fast resource provisioning | Ongoing costs can accumulate, less direct control, data residency concerns | AWS, Microsoft Azure, Google Cloud |
Hybrid | Balancing regulatory requirements with cloud scalability | Regulated data must stay on premises while less sensitive or bursty workloads need elastic cloud capacity | Flexible workload placement, compliance-friendly, scales on demand | Higher architectural complexity, integration overhead between environments | Azure Arc, AWS Outposts, Google Anthos |
Converged / Hyper-Converged (HCI) | Simplified IT management, VDI, rapid deployment | Data volume is moderate and grows in predictable steps, and a small IT team needs one platform for near-real-time workloads | Reduced hardware footprint, easy to deploy and manage | Vendor lock-in risk, scaling requires adding full nodes | Nutanix, VMware vSAN, Dell VxRail |
Edge | IoT, manufacturing, retail, any use case requiring ultra-low latency | Decisions must happen within milliseconds at the source, and sending every raw event to a central store would be too slow or too costly | Real-time local processing, reduced bandwidth costs | Limited local capacity, complex to manage across distributed sites | AWS Wavelength, Azure IoT Edge, NVIDIA Jetson |
Infrastructure Type
Traditional On-Premise
Cloud
Hybrid
Converged / Hyper-Converged (HCI)
Edge
Best For
Strict data sovereignty needs, legacy systems, predictable workloads
Cost-efficient scaling, global accessibility, minimal hardware management
Balancing regulatory requirements with cloud scalability
Simplified IT management, VDI, rapid deployment
IoT, manufacturing, retail, any use case requiring ultra-low latency
Choose It When
Analytics runs on scheduled batches, data volume is large but predictable, and data must stay on owned hardware
Data volume grows or fluctuates, and analytics needs range from batch reporting to near-real-time dashboards
Regulated data must stay on premises while less sensitive or bursty workloads need elastic cloud capacity
Data volume is moderate and grows in predictable steps, and a small IT team needs one platform for near-real-time workloads
Decisions must happen within milliseconds at the source, and sending every raw event to a central store would be too slow or too costly
Key Advantages
Full hardware and data control, no third-party dependency
Pay-as-you-go pricing, built-in redundancy, fast resource provisioning
Flexible workload placement, compliance-friendly, scales on demand
Reduced hardware footprint, easy to deploy and manage
Real-time local processing, reduced bandwidth costs
Key Limitations
High upfront costs, limited scalability, requires in-house IT staff
Ongoing costs can accumulate, less direct control, data residency concerns
Higher architectural complexity, integration overhead between environments
Vendor lock-in risk, scaling requires adding full nodes
Limited local capacity, complex to manage across distributed sites
Example Providers / Technologies
Dell PowerEdge, HPE ProLiant, Cisco UCS
AWS, Microsoft Azure, Google Cloud
Azure Arc, AWS Outposts, Google Anthos
Nutanix, VMware vSAN, Dell VxRail
AWS Wavelength, Azure IoT Edge, NVIDIA Jetson
Traditional On-Premise Infrastructure
If one has some understanding of what data infrastructure is, it is most likely they imagine a traditional one. This model involves organizations owning and managing their own servers, storage, and networking hardware in a physical data center or server room on-site.
Cloud Data Infrastructure
In contrast to on-premise infrastructure, cloud computing is fully offered by cloud service providers like AWS, Azure, or Google Cloud. This type involves computing, storage, networking, and security on-demand and online. The best parts about choosing cloud data infrastructure are its high availability since it offers robust redundancy and failover solutions and lower upfront costs since hardware investments are offloaded to the cloud provider.
Hybrid Infrastructure
As the name suggests, this type of infrastructure combines on-premise and cloud characteristics. It allows organizations to keep some workloads or data in their own data center while using cloud services for other workloads. It is especially suited for sharing storage between sensitive and general data: regulated data is best to remain on-premises, while less sensitive information can move to the cloud.
Converged and Hyper-Converged Infrastructure (HCI)
HCI is one of the digital infrastructure examples that goes one step further and groups compute, storage, networking, and other resources into integrated solutions. These solutions are typically sold as a single, pre-validated unit and deliver resources through a software-defined approach on commodity hardware.
Edge Infrastructure
This is one of the data infrastructure examples that implies locating data physically closer to where the data is generated (e.g., sensors, devices, or local servers at remote sites) rather than in a centralized data center or the cloud. It is common in IoT deployments, manufacturing, retail, and other areas requiring immediate feedback loops.

Oleksandr Boiko
Delivery Director at SPD Technology
“While each type serves its unique purpose, cloud infrastructure is the most commonly used nowadays due to cost-efficiency. Most cloud providers offer a pay-as-you-go model and do not require large upfront investments in hardware. Yet, the hybrid type comes as the second practical choice in case a business wants to secure some of their data.”
Data Infrastructure Components, Processes and Technologies
Big Data infrastructure is a complex system consisting of data lakes or warehouses, metadata, databases, server, and multiple other components, processes, and tools. To make sense of it, below are the main elements of an infrastructure.
Hardware and Software Components
For organizations to be able to store, manipulate, and process data, the infrastructure must have specific tools and processing power.
1. Software Solutions for Data Storage
The following components are responsible for managing data and documenting its context.
Infrastructure Database
Database serves as a data ecosystem within an organization. It can contain one or a set of databases (relational or NoSQL) that are used for critical applications. The infrastructure database handles real-time data manipulations and feeds data to data repositories and analytics tools.
Data Lakes, Data Warehouses and Lakehouses
Lakes, warehouses and lakehouses are the storage layers of data infrastructure, the repositories where data from operational databases lands for analysis. The difference between data warehouses and lakes comes down to the type of data each one holds and how strictly it is structured, and a lakehouse combines elements of both.
Storage Type | What It Is | Data It Holds | Schema Approach | Best Suited For |
|---|---|---|---|---|
Data warehouse | A central store of cleaned, structured data | Structured, processed data | Schema-on-write, defined before loading | BI dashboards and consistent reporting |
Data lake | A low-cost store for raw data in its original format | Structured, semi-structured and unstructured data | Schema-on-read, applied at query time | Data science, ML experiments and raw data archiving |
Data lakehouse | Lake storage with a warehouse-style management layer on top | All data types | Schema enforced through open table formats such as Delta Lake or Apache Iceberg | BI and ML on one platform without duplicating data |
Storage Type
Data warehouse
Data lake
Data lakehouse
What It Is
A central store of cleaned, structured data
A low-cost store for raw data in its original format
Lake storage with a warehouse-style management layer on top
Data It Holds
Structured, processed data
Structured, semi-structured and unstructured data
All data types
Schema Approach
Schema-on-write, defined before loading
Schema-on-read, applied at query time
Schema enforced through open table formats such as Delta Lake or Apache Iceberg
Best Suited For
BI dashboards and consistent reporting
Data science, ML experiments and raw data archiving
BI and ML on one platform without duplicating data
Data warehouse design implies predefined schemas, which makes warehouses the practical choice when most questions come from finance, sales or operations reporting on structured data. Data lakes, in turn, store data with minimal processing or schema enforcement, so they suit data science experiments, machine learning pipelines and other scenarios where a schema-on-read approach is useful. When a company needs both, a lakehouse removes the cost and sync overhead of running a lake and a warehouse side by side, which makes it a natural next step for teams that already run a lake.
Discover the step-by-step process of how to build a data warehouse in our dedicated article.
Metadata Repositories and Data Catalogs
These are the tools or systems where the company stores its information about data lineage, ownership, definitions, and relationships. Metadata repositories and data catalogs are important for two reasons: they make sure that the data stored within a company has clear definitions, and they ensure that this data uses lineage tracking. Thus, all users can easily find the data they need for analytics or reporting.
Analytics Dashboards
Dashboards are visual interfaces that present processed and assembled data in charts, graphs, and tables. They serve as representations of key information, be it KPIs, ROI, or other metrics.
2. Hardware Components
The following components are responsible for storing and running data.
Servers
Servers are integral parts of data storage infrastructure and represent physical or virtual machines that run the software needed to process and store data. They also facilitate the exchange of data between different systems.
Data Centers
Data centers are physical facilities that have numerous equipment for working with data. They serve as a core for computing and storage resources and typically include servers, storage systems, networking equipment, cooling and power management systems, as well as backup generators.
Processes
There are numerous processes happening within a Big Data infrastructure. They make sure that its data is kept in accordance with quality benchmarks, regulatory standards, and governance policies.
Database Infrastructure Design
While database infrastructure itself is a component of data infrastructure, the design of that infrastructure involves a set of decisions and structured activities, which makes it a process.
Database infrastructure design offers a structure for choosing the right database technology (relational, NoSQL, or hybrid), defining its schema, setting up hardware or cloud resources, and establishing performance, security, and scalability requirements. Having the correct design means the right performance and data integrity.
Data Infrastructure Management
This process encompasses several activities that help optimize and monitor the data environment. Data infrastructure management often includes but is not limited to such practices as patching software, updating hardware, and managing capacity demands.
Data Governance and Collaboration
Governance sets the rules for how data is accessed, used, stored and protected across a company, and collaboration makes sure those rules work for the people who rely on the data every day. Together, they keep analytics results consistent and support regulatory compliance as the number of data users grows.
Governance Roles and Policies
A workable governance model starts with named roles. Data owners are accountable for a data domain, such as customer or transaction data, while data stewards maintain its definitions, quality rules and access policies day to day. From there, the company documents policies for access, retention and lifecycle management and maps them to the regulations it falls under, such as GDPR, HIPAA or PCI DSS. Many teams formalize these rules within a broader data management framework, so governance decisions follow the same logic across every repository.
Collaboration Between Data and Business Teams
Governance holds only when the teams producing data and the teams using it agree on what each metric means. For that reason, shared business glossaries and data catalogs give engineers, analysts and business users one place to look up definitions, owners and lineage. In turn, clear request paths for new data sources or access rights keep analysts from building workarounds in spreadsheets, and agreed data contracts between producing and consuming teams make schema changes visible before they break a report.
Data Infrastructure Technologies
The toolset required for the infrastructure must allow organizations to aggregate and exchange data.
Data Integration Tools
Data infrastructure must come with tools for integration in order to streamline merging data from disparate sources into a unified format. Only with such tools, organizations can prepare data for analytics and reporting as well as the use within an organization.
Integration tools are responsible for:
- Automating Extract-Transform-Load (ETL) or Extract-Load-Transform (ELT) workflows.
- Supporting real-time or near-real-time data streams.
Networking Technologies
Tools for networking enable secure, high-speed connectivity among on-premise servers, cloud platforms, and edge devices. This type of data infrastructure technologies ensures efficient data transfer, minimizes latency, and supports distributed computing requirements.
Core networking technologies components include:
- Routers
- Switches
- Firewalls
- Load balancers
- Network links.
Modern Data Stack
A modern data stack splits the infrastructure into layers that can be chosen and replaced independently. Each layer hands its output to the next, so a gap in one of them, such as missing orchestration, shows up downstream as late or inconsistent dashboards.
Layer | What It Does | Example Technologies |
|---|---|---|
Ingestion | Moves data from apps, databases and event streams into central storage | Fivetran, Airbyte, Apache Kafka, AWS DMS |
Storage | Holds raw and modeled data for querying | Snowflake, Google BigQuery, Amazon Redshift, Databricks |
Transformation | Cleans, joins and models data into analysis-ready tables | dbt, Apache Spark |
Orchestration | Schedules and monitors pipelines and their dependencies | Apache Airflow, Dagster, Prefect |
BI and analytics | Turns modeled data into dashboards, reports and self-service queries | Power BI, Tableau, Looker |
Governance and catalog | Tracks metadata, lineage, owners and access | Collibra, Alation, DataHub |
Layer
Ingestion
Storage
Transformation
Orchestration
BI and analytics
Governance and catalog
What It Does
Moves data from apps, databases and event streams into central storage
Holds raw and modeled data for querying
Cleans, joins and models data into analysis-ready tables
Schedules and monitors pipelines and their dependencies
Turns modeled data into dashboards, reports and self-service queries
Tracks metadata, lineage, owners and access
Example Technologies
Fivetran, Airbyte, Apache Kafka, AWS DMS
Snowflake, Google BigQuery, Amazon Redshift, Databricks
dbt, Apache Spark
Apache Airflow, Dagster, Prefect
Power BI, Tableau, Looker
Collibra, Alation, DataHub
Why a Modern Data Infrastructure Is Critical for Analytics
With a robust infrastructure, big data can be effectively organized, stored, optimized, and processed, which means that it is ready to be analyzed and seen at new angles. Thus, companies can detect certain patterns and trends that highlight important information. Below, we list more benefits of a modern data infrastructure.
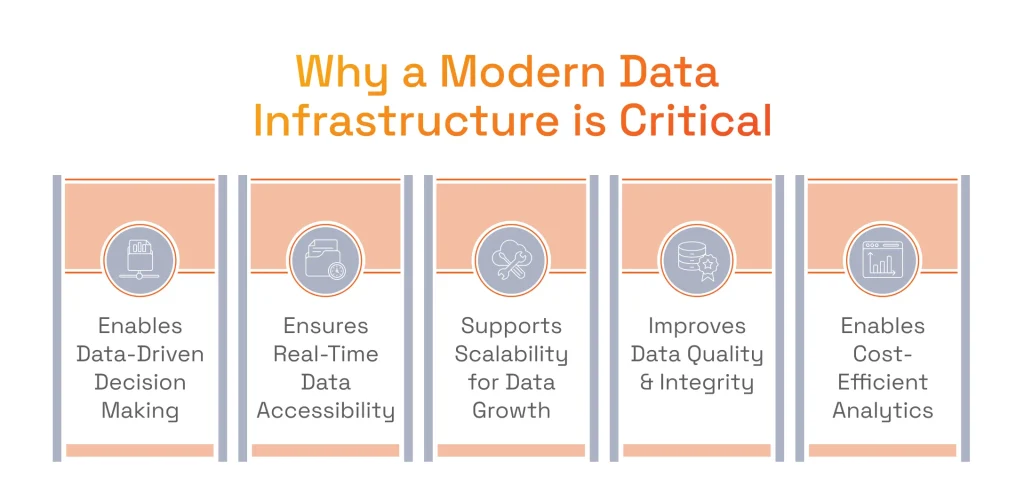
- Foundation for Data-Driven Decision Making: Having a data infrastructure means keeping the right resources for aggregating and organizing data in a single centralized place. With such an approach, organizations have access to the data as a whole and can perform its in-depth analysis. This analysis, in turn, leads to uncovering of the information that was hidden in patterns and trends.
- Enhanced Data Accessibility: Since an infrastructure has all the data in one place, all the organization’s stakeholders know where to find the information they need. Moreover, they can have specialized access that makes only relevant data available to them. With such accessibility, it becomes much easier to collaborate across departments and generate analytical outcomes.
- Scalability to Handle Growing Data Volumes: As companies inevitably grow, a solid infrastructure can accommodate this growth with scalability. This means that there will be enough storage and computing capacity to run the same analytical processes in larger volume without compromising performance.
- Improved Data Quality and Integrity: A solid infrastructure provides the possibility for effective data quality management. This means that the company introduces specific data rules that define how to keep data complete, error-free, and relevant. Such rules are designed for assisting companies in automating data cleansing and creating a one core source of truth. All these measures have a positive impact on generated analytical insights, guaranteeing their correctness and relevance.
- Real-Time Data Processing Capabilities: Today’s infrastructures empower organizations with the ability to instantly absorb and dissect data. This translates the information into immediate actions, which are essential for acting on trends and overcoming competition.
- Cost Efficiency and Resource Optimization: Big Data analytics infrastructure may seem costly at first, when setting up resources and buying storage. However, in the long run, it helps streamline data management processes and reduces redundancy. Such an efficient resource utilization makes sure that analytics operations do not require expensive additional resources.
Oleksandr Boiko
Delivery Director at SPD Technology
“Apart from the evident benefits of robust infrastructure, it is essential to note that evolving technological advancements in analytics demand more powerful resources. This is the reason why high-performance systems are indispensable for generating advanced insights, particularly through AI and ML.”
Building Data Infrastructure for Advanced Analytics: Step by Step
Building data infrastructure is a process that needs to be approached in several phases, considering multiple components and processes, and requires expertise in advanced tools. Below are common factors that should be taken into account when preparing an analytics infrastructure.
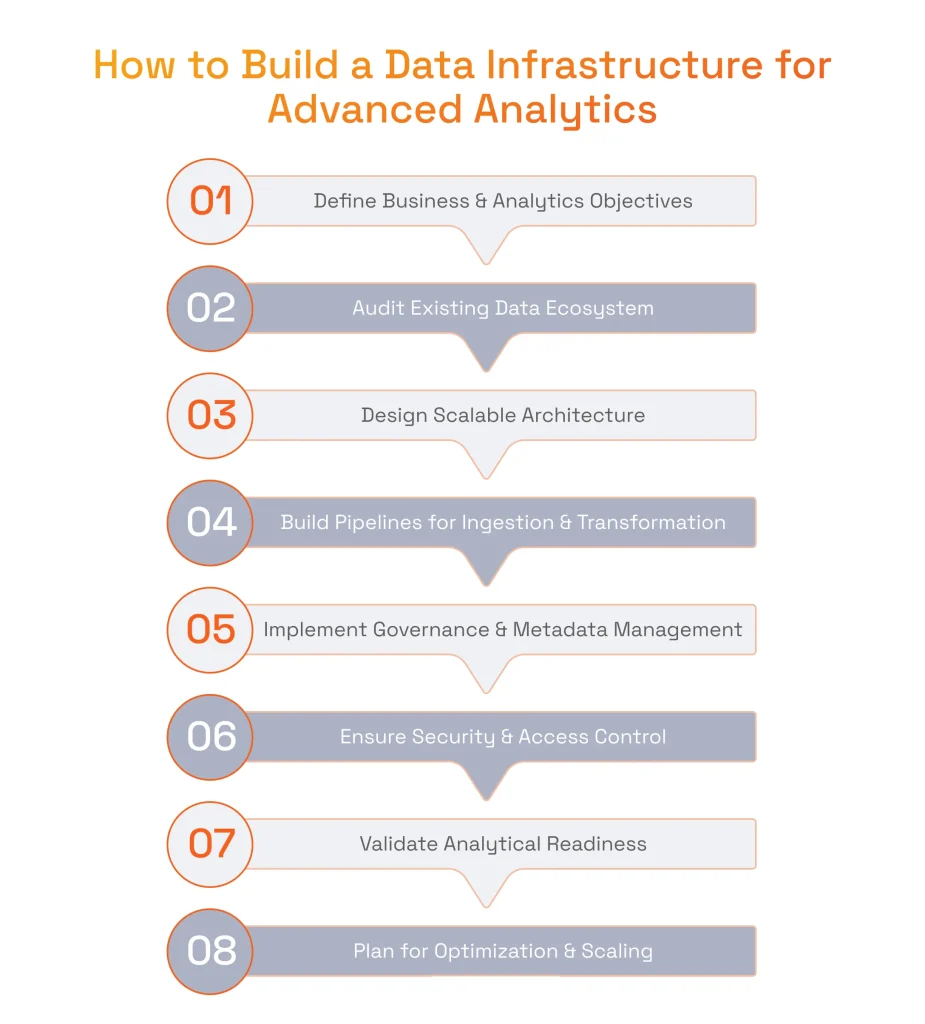
The table summarizes all the necessary steps to build data infrastructure.
Step | Owner | Output | Exit Check |
|---|---|---|---|
1. Defining business and analytics objectives | Executive sponsor with business unit heads | Prioritized list of analytics use cases with target KPIs | Stakeholders sign off on the top use cases and how success will be measured |
2. Auditing the existing data ecosystem | Head of data or data architect | Inventory of data sources, volumes, owners and known quality issues | Every source feeding a priority use case is documented with an owner |
3. Designing a scalable data architecture | Data architect | Target architecture diagram and deployment model decision | Architecture review confirms it covers projected data volume and latency needs |
4. Building data pipelines | Data engineering lead | Production ETL/ELT pipelines with monitoring and alerting | Pipelines deliver data within agreed freshness targets across a full test cycle |
5. Implementing governance and metadata management | Data governance lead with data owners and stewards | Governance policy, business glossary and populated data catalog | Every priority dataset has an owner, a definition and visible lineage |
6. Ensuring security and access controls | Security lead | Role-based access model, encryption settings and monitoring rules | Access review and security testing close with no open critical findings |
7. Validating analytical readiness | Analytics lead | Pilot or proof-of-concept results on real workloads | Query times, data consistency and scalability meet the targets set in step 3 |
8. Planning for ongoing optimization and scaling | Platform owner | Monitoring dashboard and a fixed review cadence | Capacity, cost and performance are reviewed against business growth on schedule |
Step
1. Defining business and analytics objectives
2. Auditing the existing data ecosystem
3. Designing a scalable data architecture
4. Building data pipelines
5. Implementing governance and metadata management
6. Ensuring security and access controls
7. Validating analytical readiness
8. Planning for ongoing optimization and scaling
Owner
Executive sponsor with business unit heads
Head of data or data architect
Data architect
Data engineering lead
Data governance lead with data owners and stewards
Security lead
Analytics lead
Platform owner
Output
Prioritized list of analytics use cases with target KPIs
Inventory of data sources, volumes, owners and known quality issues
Target architecture diagram and deployment model decision
Production ETL/ELT pipelines with monitoring and alerting
Governance policy, business glossary and populated data catalog
Role-based access model, encryption settings and monitoring rules
Pilot or proof-of-concept results on real workloads
Monitoring dashboard and a fixed review cadence
Exit Check
Stakeholders sign off on the top use cases and how success will be measured
Every source feeding a priority use case is documented with an owner
Architecture review confirms it covers projected data volume and latency needs
Pipelines deliver data within agreed freshness targets across a full test cycle
Every priority dataset has an owner, a definition and visible lineage
Access review and security testing close with no open critical findings
Query times, data consistency and scalability meet the targets set in step 3
Capacity, cost and performance are reviewed against business growth on schedule
Defining the Business & Analytics Objectives
The first and foundational step is to define what aspect of business data analytics will cover. Businesses may want process optimization, deeper understanding of what customers expect from the company, or looking for new revenue opportunities. No matter the goal, the company’s stakeholders must agree on one or several objectives, since it will help to further define what the company expects to achieve with new data analytics initiatives. Consequently, all the investments into a new infrastructure will be completely justified.
Auditing Existing Data Ecosystem
The systems, databases, and analytical tools that are already in place are a valuable foundation for the future infrastructure. However, to make sure the infrastructure conforms to every requirement data analytical processes may have, it is important to evaluate the data sources, volumes, and complexity of the existing ecosystem. This is a necessary step as it can highlight redundant processes and inefficiencies for the technical team to address and eliminate. As a result of such an audit, companies get the chance to upgrade or replace legacy elements that prevent a data infrastructure platform from performing seamlessly.
Designing a Scalable Data Architecture
When it comes to data architecture, two of the most vital factors to consider should be handling growing data volumes and evolving business needs. For this, companies need to select appropriate storage solutions, like an enterprise data warehouse, choose between on-premise, cloud, or hybrid deployments, and determine how best to integrate streaming or batch processing. Approaching all of these factors beforehand and with careful consideration will guarantee that the company will not make large additional investments in resources in the process.
Building Data Pipelines for Ingestion & Transformation
Pipelines can be considered the lifeblood of data analytics because they are responsible for moving information securely from different sources to a single place. The whole process needs to be gentle with data in order not to corrupt it. This is why these pipelines typically have ETL or ELT processes, as they cleanse, standardize, and enrich data. With these processes in place, as well as automated and set up for real-time workflows, data infrastructure design is considered optimal for reliable data analytics with minimal latency and a continuous flow of up-to-date insights.
Implementing Strong Data Governance & Metadata Management
Even though there is no correct analytics without data governance, Deloitte’s 2025 CDO Survey found that while 51% of CDOs rank data governance as their top priority, 47% say competing organizational priorities hinder their ability to realize the full value of data. This gap can be an actual benefit for organizations that prioritize data governance and metadata management to gain an advantage over competitors. They need to define the rules of how their data is accessed, shared, and maintained across an organization, as well as outline data lineage and definitions to guarantee the management of metadata.
Ensuring Security & Access Controls
No matter if a company builds an enterprise data infrastructure or a smaller one, ensuring its security is essential for keeping intellectual property and customer information safe. This is why encryption at rest and in transit, role-based access, and continuous monitoring for suspicious activity must be prioritized.
Validating Analytical Readiness
Before rolling out analytics solutions, it’s crucial to validate that the data, infrastructure, and tools can support accurate and performant insights. This involves either pilot studies or proof-of-concept projects to check data consistency, system scalability, and query response times. Successful validation provides confidence that the analytics platform will meet both current and anticipated workloads.
Planning for Ongoing Optimization & Scaling
Since the evolution of a business almost always implies growth, companies must take care that available resources are accommodating the data perfectly and do not create performance bottlenecks. Organizations should establish a framework for monitoring performance, which will help to identify new data sources and update data models or tools as new business requirements appear.
Challenges of Setting Up a Data Analytics Infrastructure
Most companies run into a familiar set of obstacles when they set up an analytics infrastructure, and each one has a resolution that SPD Technology applies on client projects.
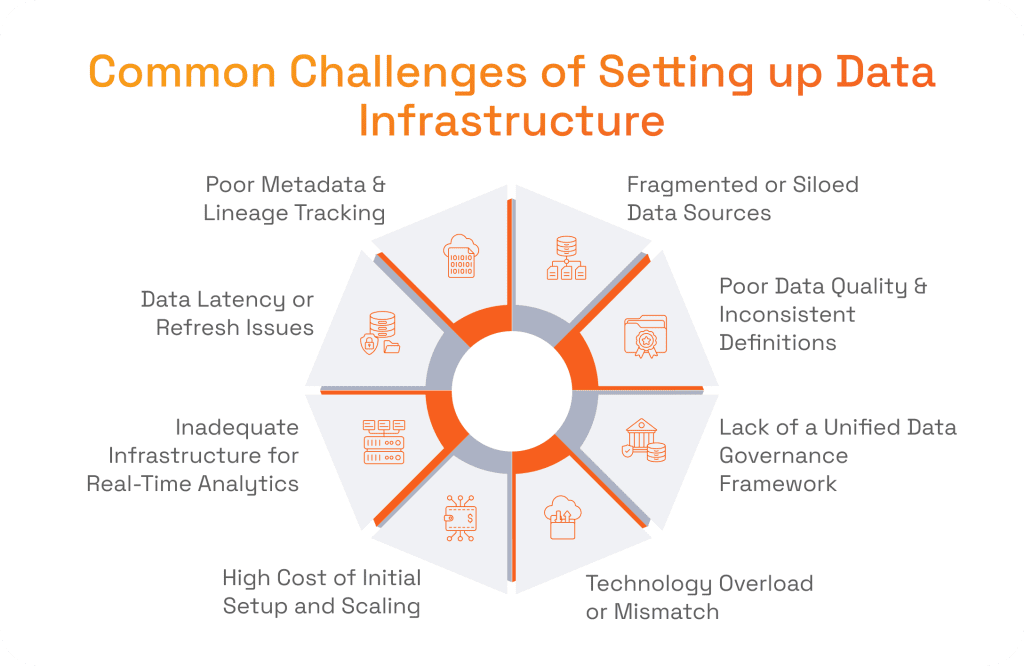
Fragmented or Siloed Data Sources
Gartner research found that 63% of organizations either do not have or are unsure if they have the right data management practices for new technologies, including AI, predicting that through 2026, organizations will abandon 60% of AI projects unsupported by the right data. We can support these statistics with our experience, as we see that our clients often work in multiple ERP platforms, CRM tools, departmental databases, and various SaaS applications, which are not connected to the same repository. As a result, all employees can not use data analytics to their full potential: generated insights end up to be incomplete or duplicated.
We typically overcome silos thanks to:
- Mapping which systems hold the same entities, such as customers or orders, and agreeing on one master source for each.
- Consolidating those entities into a shared data model in the warehouse or lake.
Poor Data Quality & Inconsistent Definitions
Gartner found out that poor data quality costs companies around $13 million a year on average. At the same time, our clients often report that they have difficulties with validating and cleaning their data without the help of a technical expert. As a result, they cannot fully leverage analytics or encounter misleading analytical results.
To help companies improve data quality, we suggest:
- Establishing data quality standards and automated validation checks.
- Using data profiling tools to identify and remediate errors in source data.
- Having a data management strategy in place to know how to standardize data and keep an eye on its quality.
Explore important criteria to include into an effective data management strategy in our dedicated article!
Lack of a Unified Data Governance Framework
Our clients that are seeking to establish analytical processes often lack a governance framework that must be an integral part of data infrastructure strategy. These companies do not have a clear understanding of ownership, responsibilities, and policies around data usage. Such a lack of governance can result in security breaches and regulatory violations.
In such cases, we typically suggest:
- Starting with the domains that carry the highest regulatory risk, such as payment or patient data, and assigning owners there first.
- Mapping existing access rights against the new policies to close gaps before analytics goes live.
Technology Overload or Mismatch
Some of our clients tried using a number of analytics tools within a company and ended up with inefficiencies. Some features overlapped or did not integrate well with their existing business systems. In the end, they were not satisfied with the outcomes of data analytics, as those were duplicated, complex, or confusing.
When it comes to overload or mismatch of technologies, we offer our clients to:
- Conduct assessments of business requirements before tool selection.
- Consolidate or standardize technologies where practical.
- Consider scalability and integration during vendor evaluations.
High Cost of Initial Setup and Scaling
Hardware, software licenses, and training personnel often require companies to spend a lot of money in the first month of setting up data analytics. Some of our clients had concerns about these investments, making them doubt the adoption of analytics. What’s more, costs can escalate quickly if the infrastructure has to be scaled for large data volumes or for complex real-time analytics.
To help organizations optimize these expenditures, we often offer to:
- Leverage the benefits of cloud computing infrastructure to reduce initial expenses.
- Adopt a modular architecture to expand capacity on demand.
- Prioritize high-impact use cases that can demonstrate early value.
- Utilize open-source technologies and managed services where appropriate.
Inadequate Infrastructure for Real-Time Analytics
Our clients with established businesses often have legacy systems that are not capable of supporting real-time or near real-time capabilities. Their systems are typically built around batch processing models and have limited streaming data ingestion, outdated APIs, and inadequate mechanisms for low-latency data transformations.
The following practices help us to set up data analytics real-time capabilities for our clients:
- Deployment of streaming data platforms (e.g., Kafka) for real-time ingestion.
- Implementation of in-memory processing and optimized data stores for low-latency analytics.
- Usage of distributed compute frameworks that can scale to handle large event streams.
- Implementation of caching strategies to deliver faster insights to end users.
Data Latency or Refresh Issues
There are cases when our clients complain that they missed critical updates or respond too slowly to emerging trends. Yet, they do not know why. After auditing their platforms, we usually find that the reason for that is stale data in their analytics dashboards and reporting systems. This is commonly caused by inefficient data pipelines, batch-only processes, or connectivity issues between data sources and the analytics environment.
To overcome these issues, we focus on:
- Optimizing ETL/ELT processes to reduce load times, for example through parallelization.
- Adjusting data refresh schedules to match how often each dashboard is actually used.
Poor Metadata & Lineage Tracking
A lack of clear metadata and data lineage makes it difficult for our clients to understand where data originates, how it transforms, and how it is used downstream. This is why they often turn to us for help with troubleshooting, root-cause analysis, and regulatory compliance.
To resolve these issues and prevent them from happening in the future, we do the following:
- Implementing cataloging tools that harvest metadata automatically, so lineage stays current without manual documentation.
- Linking lineage records to compliance reporting, so auditors can trace any figure back to its source.
How SPD Technology Supports Data Infrastructure and Analytics Projects
Large-scale data platforms combine distributed systems, security protocols, pipelines and cloud cost management, and a configuration error at that scale can quickly turn into downtime or data loss. For that reason, many companies bring in an external team when their internal engineers know their own product well but have less hands-on experience with data platform engineering.
SPD Technology’s data analytics services cover the full data stack, from ingestion and storage in warehouses or lakes to ETL/ELT transformation and analytics. Most projects run on cloud-native architectures, though the team also sets up on-premise and hybrid environments when regulation or existing systems require it. Each initiative starts with data strategy consulting, which ties the work to a defined business use case, and security work follows the regulations a client operates under, including GDPR, HIPAA and PCI DSS. Beyond analytics, the same pipelines and storage are prepared for ML models and real-time workloads, drawing on the company’s AI/ML development work in finance, healthcare and eCommerce projects.
The HaulHub Case: Data Infrastructure and Analytics for Transportation Construction
HaulHub, a US-based transportation construction company, needed help building a unified digital platform for agencies, contractors, vendors and suppliers.
Business Challenge
The client set up the handling of their mission-critical workflows like digital ticketing, field inspections, and real-time project tracking. However, HaulHub also needed assistance scaling its data infrastructure to ingest large volumes of ticket data and integrate advanced AI features. They also faced the challenge of integrating disparate legacy code and ensuring tight security and compliance measures for sensitive construction and transportation data.
SPD Technology’s Approach
Our team started with overhauling the existing agency collaboration component of the entire system by analyzing existing code, implementing robust data pipelines, and optimizing the platform’s data architecture for high-volume loads.
Afterward, we developed mobile and web apps using Java with Quarkus on AWS Lambda, complemented by native iOS/Android builds for peak performance. We applied our data engineering best practices, such as AWS Database Migration Service, ETL tools, and advanced caching, to enable near real-time analytics across tens of millions of ticketing records. We also integrated AI/ML capabilities (OpenAI ChatGPT, AWS Bedrock) to streamline operations like automated reporting, image processing, chatbot interactions, and traffic analysis.
Value Delivered
The work resulted in an AI-powered, data-driven ecosystem for the transportation construction industry that gives agencies, contractors, vendors and suppliers across the United States digital ticketing, automated inspections and real-time analytics.
Key Takeaways
- Global data center spending is projected to surpass $788 billion in 2026, according to Gartner. That investment pays off for analytics only when governance, integration and quality controls are built in from the start.
- The infrastructure type should follow analytics latency and data volume:
- On-premise fits scheduled batch analytics on large, predictable volumes that must stay on owned hardware.
- Cloud fits growing or fluctuating volumes.
- Hybrid keeps regulated data on premises while drawing on cloud capacity.
- HCI suits moderate, predictable growth managed by a small IT team.
- Edge handles decisions that must happen within milliseconds at the source.
- Warehouses, lakes and lakehouses are storage layers within data infrastructure. Warehouses serve structured reporting, lakes keep raw data for data science and ML, and lakehouses bring both workloads onto one platform.
- Gartner research shows that 63% of organizations lack, or are unsure they have, the right data management practices for AI. It predicts that through 2026, organizations will abandon 60% of AI projects unsupported by the right data, which makes infrastructure readiness a prerequisite for any AI or analytics initiative.
- Deloitte’s 2025 CDO Survey found that 51% of CDOs rank data governance as their top priority, while 47% say competing priorities keep them from realizing the full value of data. Named data owners and stewards, shared glossaries and data contracts between teams help close that gap.
- Building data infrastructure works best in eight phases, from defining business objectives to ongoing optimization. Each phase has a named owner, a concrete output and an exit check before the team moves on.
In short: data infrastructure determines whether analytics, AI and real-time insights are possible at all, so it deserves the same planning as the analytics built on top of it.
FAQ
How much does building a modern data infrastructure from scratch cost?
Costs vary widely by scale and deployment model.
- A cloud-based setup for a mid-size company typically runs $50,000-$300,000 in the first year, covering pipelines, storage, governance tooling, and integration work.
- Enterprise-grade infrastructure with real-time analytics, AI/ML readiness, and multi-region redundancy can exceed $1-3 million.
What are the most common data infrastructure mistakes that create technical debt?
The most common are:
- choosing tools before defining requirements;
- skipping data governance until problems appear;
- building monolithic pipelines that can’t scale;
- neglecting metadata and lineage tracking;
- underinvesting in data quality validation.
Each creates compounding downstream costs. Poor governance alone averages $13 million per year in quality-related losses. So, infrastructure built to solve today’s problem without tomorrow’s growth in mind requires partial or full redesign within 2-3 years.
How long does it take to build scalable data infrastructure for a growing company?
A phased approach typically spans 6-18 months. The first 0-3 months establish data warehouse foundations and governance frameworks. Months 3-9 cover pipeline development, integration, and quality validation. Real-time capabilities and AI/ML readiness come in months 9-18. Trying to compress this timeline by skipping governance or validation phases consistently produces performance issues and data quality problems that require rework.
What happens when a company outgrows its data infrastructure?
Performance degrades first: queries slow, dashboards lag, and pipelines miss SLAs. Then analytical accuracy suffers as data volumes exceed what legacy systems can properly validate or govern. Organizations typically respond with expensive emergency scaling, tool replacements, or full re-architecture. The outcome is avoidable: infrastructure designed with modular, cloud-native architecture and monitoring frameworks can scale incrementally without the disruption that batch-processing legacy systems create when pushed beyond their capacity.
What is the difference between a data warehouse, data lake, and data lakehouse?
A data warehouse stores structured, processed data with predefined schemas, which is ideal for BI and consistent reporting. A data lake stores raw structured, semi-structured, and unstructured data with minimal processing, suited for data science and ML experimentation. A data lakehouse combines both: it adds warehouse-style governance and query performance on top of a lake’s flexible storage, enabling a single platform for both analytics and ML workloads without maintaining two separate systems.